- Optimization Type
- Policy
- Monthly Waste
- Effort
- Instance Type
- Monthly Cost
- CPUs
- CPU Benchmark
- Memory (GB)
When you click the button, a popup opens with a link. You can save or download the file.
The filename will be `
- Cloud Provider
- Service Type
- System Name
- Instance ID
- Instance OS
- Account Name/ID
- Region/Availability Zone
- A tabular report--A configurable tabular report is shown in the top pane. Descriptions of each column are provided in Analysis Details Table tabular data.
- Utilization Charts--Based on the system selected in the top pane, the corresponding utilization charts are shown in the lower pane. See Analysis Details Utilization Charts for details on expanding, configuring and interpreting the utilization charts
- Enter your search criteria in the search bar, located in the upper right of the page.
- The table contents update as you enter your search parameters.
- Click the X in the search box to clear the search parameters.
- Select the table view and adjust views and filters to obtain the desired set of data.
- Click the export icon, located beside the **Table View** drop down menu.
| System View | View | Column |
|---|---|---|
| N/A | Default View | This is the most commonly used set of columns that provide a summary view of your cloud instances. Significant risks or wasted spend are highlighted. |
| N/A | All Data | All columns and all data, as defined by your tree viewer selections are displayed. All filters are cleared. Horizontal and vertical scroll bars are displayed so you can navigate the content of the table. |
| Cloud Provider | AWS | This view shows all AWS EC2, RDS and ASG instances. |
| Azure | This view shows all Azure VM and VMSS instances. | |
| GCP | This view shows all GCP Compute instances. | |
| Optimization Type | Downscale | This view displays all services of the specified optimization type within the selected scope, as defined by the tree viewer. i.e. Downsize, Upsize, etc. |
| Downsize | ||
| Modernize | ||
| Terminate | ||
| Upscale | ||
| Upsize | ||
| Service Type | AWS ASG | This view displays all services of the specified type within the selected scope, as defined by the tree viewer. |
| AWS ECS | ||
| AWS RDS | ||
| Azure VM | ||
| Azure VMSS | ||
| GCP - Compute Engine |
|
Column Name |
Description |
Available For |
||||||
|---|---|---|---|---|---|---|---|---|
|
Cloud Provider |
The name of the public cloud provider. |
All supported services |
||||||
|
The type of service being analyzed. Not all service types are supported.
|
All supported services |
|||||||
|
Account Name |
The instance's parent account. This corresponds to:
|
All supported services |
||||||
|
System Name |
The name of the selected system. The name is a hyperlink that opens modal view with a detailed summary of the instance and comparison of the current and recommended instance types. |
All supported services |
||||||
|
Region |
The region, in which this instance is located. |
All supported services |
||||||
|
Identifies the overall status of the optimization results based on Optimization Type and potential Analysis Details Table:
|
All supported services |
|||||||
|
Instance Type |
The current instance type, based on data collection. |
All supported services |
||||||
|
Recommended Instance Type |
This is the recommended catalog instance type is listed, based on the optimization analysis. |
All supported services |
||||||
|
This is the per instance cost per month, for the current instance type, corresponding to the listed Analysis Details Table type for on-demand usage. Calculated as: Catalog Price \* Uptime |
All supported services |
|||||||
|
This is the per instance cost per month, for the recommended instance type, corresponding to the listed Analysis Details Table type for on-demand usage. Calculated as: Catalog Price \* Uptime |
All supported services |
|||||||
|
\$Total Waste/Month |
The current and recommended estimated instance cost is used to calculate savings per month. Calculated as: (current estimated cost - recommended estimated cost).
|
All supported services |
||||||
|
%Waste/Month |
The savings/month expressed as percentage of the current cost, for this instance. Calculated as: (current estimated cost - recommended estimated cost)/current estimated cost \*100. |
All supported services |
||||||
|
System ID |
A unique key assigned by the public cloud vendors to identify this instance. |
All supported services |
||||||
|
Account ID |
A unique key assigned by the public cloud vendors to identify the account. |
All supported services |
||||||
|
This column describes the effort required to investigate and implement the recommendation. Effort will be one of : Moderate | Low | Very Low | None Effort for each instance is calculated using rule-driven analytics based on factors, such as instance family change, storage change, data quality checks, feature changes, etc. These factors can be configured through the policy settings that capture your best practices. Click on the Effort Details tab to view the factors that contribute to the effort level. See Reviewing the Workload Charts and Additional Details Tabs, below. |
All supported services |
|||||||
|
Availability Zone |
The cluster/availability zone that corresponds to a geographic region. |
All supported services |
||||||
|
OS |
The operating system running on this instance. The operating system running on all scale set instances. |
All supported services |
||||||
|
Instance Creation Date |
The date on which this instance, was first created in your public cloud account. |
All supported services |
||||||
|
Instance Discovery Date |
The date on which data was first collected from this instance, by Kubex. |
All supported services |
||||||
|
Power State |
The power state of the selected instance. |
All supported services |
||||||
|
K8s Cluster |
This column indicates the name of the Kubernetes cluster that the scale group is hosting. When populated the analysis requires additional information to ensure the scale group can satisfy all of the container requests. If the column "K8s Node Group" is populated with a dash (-) or the column is not visible, then consider deploying the Kubex data collector into this cluster to collect the required data. Note: This column is displayed only if the scale group is hosting a Kubernetes cluster. |
|
||||||
|
K8s Cluster (from Kubex Agent) |
This column indicates the name of the Kubernetes cluster, as configured in the Kubex data collector. Note: This column is displayed only if the scale group is hosting a Kubernetes cluster. |
|
||||||
|
K8s Node Group |
This column indicates the name of the Kubernetes node group associated with this scale group. When populated, Kubex has the data required for enhanced scale group analysis. Note: This column is displayed only if the scale group is hosting a Kubernetes cluster. |
|
||||||
|
ECS Cluster |
The name of the ECS cluster hosted by this Auto Scaling group. The additional cluster-level information is used for enhanced ASG analysis, resulting in more accurate recommendations. Note: This column is available only if the Auto Scaling group is hosting an ECS instance. For ECS services, capacity providers can be used to manage the infrastructure that the tasks in your clusters use. Capacity providers for ECS allow for multiple ASGs to support an ECS cluster. The reference in this column accounts for created capacity providers and indicates the ECS service cluster that is associated with this ASG. There will be an impact to the effort value for ASGs, hosting a Kubernetes cluster, and not linked with a ECS/EKS reference (i.e. has no parent). |
|
||||||
|
Policy |
The policy used to analyze the data and generate the recommendations. |
All supported services |
||||||
|
The recommended action for this instance. See Details - Optimization Type Descriptions and Color-Coding for a description of each optimization type. |
All supported services |
|||||||
|
Recommendation Reason/Observations |
The reason for the Optimization Type recommendation. Kubex also provides any relevant details related to the recommendation. |
All supported services |
||||||
|
A value in this column indicates that the instance type was changed recently. The recommendation for this instance is based only on workload data collected from the specified date, onward. Any historical data gathered before this date is excluded from the analysis, as it has been collected from a different instance type and is no longer relevant. A blank cell indicates the current instance type has not changed and all available workload data within the range, defined by the policy, has been used to generate the recommendation. |
All supported services |
|||||||
|
This is the percentage of reserved instance (RI) coverage available for the current instance. Flexible RIs are taken into consideration when calculating the percentage of RI coverage. However, convertible RIs are included in the calculation depending on the RI coverage assessment Kubex settings. For individual compute or database instances, the coverage percentage is either 100% or 0%. Coverage between 0 and 100% occurs when Flexible RIs are converted into partial coverage. Contact [support@kubex.ai](mailto:support@kubex.ai) to review your RI candidate policies and RI coverage assessment Kubex settings. |
|
|||||||
|
Defer recommending an instance type change until reserved instance coverage for this instance expires. Values include:
An icon on this column indicates that instances that are RI-constrained should not be modified to the recommended instance type at this time, since the current instance has existing reserved instance coverage. When the applicable reserved instances expire (as indicated by the "Current RI Expiry Date"), then the instance can be modified to the recommended instance type. Contact [support@kubex.ai](mailto:support@kubex.ai) to review the setting for "AWS Defer Recommendations". . |
|
|||||||
|
Current RI Expiry Date |
If Defer Recommendation Until Current RI Coverage Expires = Yes, then the expiry date of the reserved instance, currently providing coverage for this instance, is displayed. This value is only applicable to AWS EC2, RDS instances. Note: The RI expiry date is not displayed for an instance with Optimization Type= "Just Right" or "Terminate" . |
|
||||||
|
Scaling Mode |
The scaling mode applied to this VM Scale Set. The scaling mode can be one of manual or autoscale. If the VM Scale Set is currently running in manual mode, consider changing it to autoscale mode. If, enabled, historical audits only apply to s set to "auto" and do not include s set to "manual". Data for s set to "manual" is only collected on a daily basis and the required number of days, as defined by the policy, must be collected before recommendations are displayed in the UI.The proposed recommended instance type, minimum and maximum group size are based on scaling mode being set to autoscale. If, enabled, historical audits only apply to VM Scale Sets set to "auto" and do not include VM Scale Sets set to "manual". Data for VM Scale Sets set to "manual" is only collected on a daily basis and the required number of days, as defined by the policy, must be collected before recommendations are displayed in the UI. This value is only applicable to Azure instances VM Scale Sets. |
|
||||||
|
No. of Profiles |
The number of profiles associated with the selected VM Scale Set. Profiles are only applicable to scale sets with scaling mode=Autoscale. By default, scale sets with orchestration mode=Uniform are created with one scaling profile. Multiple profiles can be used to scale in different ways at different times. If for example, your workloads are inactive on some weekends, a recurring profile to scale in resources can be applied. |
|
||||||
|
Orchestration Mode |
The orchestration mode applied to this VM Scale Set. The orchestration mode can be one of Uniform or Flexible. Only Uniform scale sets, or Flexible scale sets running identical instance types are analyzed. See Details - VM Scale Set Mixed Mode Services for details. The proposed recommended instance type, minimum and maximum group size are based on the orchestration mode being set to uniform. |
|
||||||
|
When using pay-per-use pricing models, the amount of time each instance has been running, is required to accurately estimate future costs. The predicted uptime (%) for a cloud instance or container, is based on the percentage of hours CPU utilization data is present in the historical interval, as specified in the policy settings for the entity. For Auto Scaling groups and VM Scale Sets and Individual child instances are not taken into account. Uptime for new instances or containers, that started mid-way through the historical interval, is calculated from the time/date that the instance was started rather than the beginning of the interval, resulting in more accurate predictions for future usage. For example, the uptime is the number of hours that have "CPU Utilization in mcores", and the range is the lesser of when the container was discovered, or the range that is defined in the policy. Looking at a specific container that was discovered on July 5th 2025, that has workload for 42 hours since that date, then 13 days later, the uptime % is 42 hrs/(13 days x 24 hrs/day) = 13.4%. This is the value reported in this column. When determining the uptime for Auto Scaling groups and VM Scale Sets individual child instances are not taken into account. |
All supported services |
|||||||
|
Total Hours |
The total hours that the instance has been in the environment. |
All supported services |
||||||
|
Running Hours |
The number of hours that the instance has been running. |
All supported services |
||||||
|
Avg Group Size |
The average instance count when the scale group is running. |
|
||||||
|
The minimum number of instances/hour. For VM Scale Set, when configured to autoscale, this value is the minimum of all the profiles associated with the selected VM Scale Set. When configured to scale manually, this is the minimum number of instances found during the historical period that is used for the analysis. The historical period is defined by the policy setting, "Workload range". |
|
|||||||
|
This is the maximum number of instances/hour. For VM Scale Set, when configured to autoscale this value is the maximum of all the profiles associated with the selected VM Scale Set. When configured to scale manually, this is the maximum number of instances found during the historical period that is used for the analysis. The historical period is defined by the policy setting, "Workload range". |
|
|||||||
|
The predicted, average instance count on the recommended instance type. |
|
|||||||
|
Recom. Min Group Size |
The recommended minimum number of instances for the selected scale group. |
|
||||||
|
Recom. Max Group Size |
The recommended maximum number of instances for the selected scale group. |
|
||||||
|
This value indicates whether the scaling mode needs to be reviewed. Possible values depend on whether or not the VM Scale Set is managed by AKS: * VM Scale Set is managed by an AKS cluster: * No Value – If the optimization type = Terminate, then: * In the UI, a dash, "--" is displayed. * In the API, "Terminate" is returned in the /results. * Keep – If the current average group size is the same as the recommended average group size.\ The optimization type = Just Right. * Review – If Kubex recommends changing one or more of instance type, average, minimum or maximum group size. * VM Scale Set is NOT managed by an AKS cluster: * No Value – If the optimization type = Terminate, then: * In the UI, a dash, "--" is displayed. * In the API, "Terminate" is returned in the /results. * Keep – If the current average group size, minimum and maximum group size are not changed.\ The optimization type = Just Right. * Review – If Kubex recommends changing one or more of instance type, average, minimum or maximum group. * Enable Autoscale – If Kubex recommends changing one or more of instance type, average, minimum\ or maximum group size and the VM Scale Set is not managed by AKS. * Adjust – If the current average group size is not the same as the predicted average group size **AND**\ instance type and minimum and maximum group size do not change **AND** the VM Scale Set is not managed by AKS. |
|
|||||||
|
Life Cycle |
This is the instance market option configured for an Auto Scaling group.
|
|
||||||
|
Current CPU |
The current CPU allocation for the selected instance. |
All supported services |
||||||
|
Recommended CPU |
The recommended CPU allocation for the selected instance. |
All supported services |
||||||
|
Current CPU Benchmark |
The CPU benchmark for the current instance type. |
All supported services |
||||||
|
Recommended CPU Benchmark |
The CPU benchmark for the recommended instance type. |
All supported services |
||||||
|
vCPU Surplus |
The change in actual vCPUs that will result if the recommendation is made. |
All supported services |
||||||
|
Recommended CPU Benchmark |
The CPU benchmark for the recommended instance type. |
All supported services |
||||||
|
Current Memory
|
The current memory allocation for the selected instance. |
All supported services |
||||||
|
Recommended Memory Allocation (GB) |
The recommended memory allocation for the selected instance. |
All supported services |
||||||
|
Network IO Throughput MB/s (current) |
The network throughput in MB/s for the curernt instance. |
All supported services |
||||||
|
Network IO Throughput pkts/s (current) |
The network throughput in pkts/s for the current instance. |
All supported services |
||||||
|
% CPU Usage Current |
The percentage of current CPU allocation that is used by the workload, on the selected instance. |
All supported services |
||||||
|
% Memory Usage Current |
The percentage of active memory allocation that is used by the workload, on the selected instance. |
All supported services |
||||||
|
% CPU Usage Recommended |
The percentage of the recommended CPU allocation that would be used by the workload, on the selected instance. |
All supported services |
||||||
|
% Memory Usage Recommended |
The percentage of the recommended active memory allocation that would be used by the workload, on the selected instance.instance. |
All supported services |
||||||
|
IP Address |
The IP address of the selected instance. |
All supported services |
||||||
|
Summary Total |
In the top-right of the tabular report, the total number of Instances and Savings/Month for implementing the recommendations are displayed. The amount of savings per month is a sum of all the monthly savings for each instance listed and can be negative if the recommendation is an upsize or upsize to an optimal family. |
All supported services |
| Optimization Type | Description |
|---|---|
| Just Right | This instance is optimally sized for the workload. |
| In general the following upsize recommendations incur additional costs. The cost increase is determined by comparing on-demand pricing for the current and recommended instance. The increased cost is required to alleviate application risk. If you have an RI or SP for the recommended upsize instance, there could be cost savings. This would still be an upsize recommendation. | |
| Upsize - Optimal Family |
This indicates the instance should be upsized to a more optimal instance family. This will improve the workload's performance and reduce risk.
If the workload can be moved to larger instance in a different family and still reduce cost, this then becomes a Modernize recommendation. e.g. t2.medium-Linux to m3.medium-Linux |
| Upsize |
This indicates the instance should be upsized to an instance within the same instance family. The hosted workload needs an instance with more CPU and/or memory resources.
e.g. r3.large to r4.xlarge, both are in the "Memory Optimized" instance family. |
| Upscale |
This indicates the maximum group size for the Auto Scaling group or VM Scale Set should be increased for additional compute capacity.
It may be more cost effective to use a larger instance instead of increasing the group size, for this Auto Scaling group or VM Scale Set. |
| Downsize recommendations reduce the allocated resources as your workload has likely been over-provisioned. Once the recommendation has been determined from CPU and memory utilization, it is further verified against policy-defined limits, before the downsize or terminate recommendations are made. | |
| Terminate | This indicates the instance should be terminated, as it is idle. An instance is determined to be idle if it has very low CPU utilization, network and disk I/O over an extended period of time. This will save you money. |
| Downsize - Optimal Family |
This indicates the instance should be downsized to an instance belonging to an instance family that more closely suits your workload's utilization.
When you downsize, CPU and/or memory will be decreased to better suit your workloads. Utilization will improve with no impact on performance. This will save you money. e.g. d2.medium-Linux to m4.medium-Linux |
| Downsize |
This indicates the instance should be downsized to an instance within the same instance family.
As indicated above, CPU and/or memory will be decreased to better suit your workloads. Utilization will improve with no impact on performance. This will save you money. e.g. m3.large-Linux to m3.small-Linux |
| Downscale | This indicates the instance the Auto Scaling group or VM Scale Set should be downscaled to decrease the compute capacity by adjusting the maximum and/or minimum group size. |
| The following modernize recommendations move your workload to a more modern instance type without changing the resource allocation, cost or performance, at a minimum. Your costs could decrease and/or you may benefit from potential utilization and performance improvements. | |
| Modernize - Optimal Family |
This indicates the instance should be modernized to an instance belonging to a more optimal instance family. The cost of the new instance type will be less than the existing cost.
Allocated resources are not being removed and moving to an instance with more current hardware, you may also benefit potential utilization and performance improvements. When you modernize, you will not decrease performance but will decrease cost. |
| Modernize |
This indicates the instance should be modernized to an instance within the same instance family. The cost of the new instance type will be less than the existing cost and as indicated above you may also get utilization and performance improvements.
For example, moving to a new generation of the same instance family (e.g. m3.large to m4.large). |
- Child instances are a combination of different instance types;
- Child-instances differ from what is defined in the launch template/configuration/scale set model for the ASG or VM Scale Set .
- Mixed Policy is not set/Orchestration Mode = Uniform and all running instance types are the same.
- When the instance type defined for the ASG or VM Scale Set and child-instance types are the same and all running instance types are the same.
All Instance Types
- CPU Utilization (%) Current
- CPU Utilization (%) Recommended
- CPU Utilization - Busiest Day (%) Current
- CPU Utilization - Busiest Day (%) Recommended
- Memory Utilization (%) Current
- Memory Utilization (%) Current
- Disk I/O (Bytes/s)
- Disk I/O (Operations/s)
- Network I/O (Bytes/s)
- Network I/O (Packets/s)
Scale Sets Only
- In Service Instances (Current)
- In Service Instances (Recommended)
- CPU Request (%) (Current)
- CPU Request (%) (Recommended)
- Memory Request (%) (Current)
- Memory Request (%) (Recommended)
| Setting | Default | Description |
|---|---|---|
| Show Instance Types that are: | Commonly used options, that are available in the selected region are shown as a comma-separated list |
Select one or more of the following options to filter the list of instance types to be displayed in the catalog map.
|
| Processor Supplier | All |
Select one or more of the following options to filter the list of instance types to be displayed in the catalog map.
|
| Spend Tolerance | 5X more than optimal | Specify a spend tolerance value that determines cost compatibility. For example, selecting a value of 20% means that instance types that cost up to 20% more than the optimal instance type are considered compatible. You can choose a spend tolerance ranging from the exact cost of the optimal instance (No more than optimal) to no cost limit (Unlimited). Spend tolerance impacts the compatibility status of instance types that are technically compatible based on resource requirements. If an instance exceeds the specified spend tolerance, it will be shown in yellow to indicate it is technically compatible but not cost-efficient. As you increase the spend tolerance, more instance types will be within the acceptable range and change from yellow to green, indicating both technical and cost compatibility. |
| Highlight Instance Features | Select one or more instance features that may improve the performance of your workload. Values displayed in this dropdown are based on the selected region and cloud provider. Selections are shown in the dropdown window as comma-separated values. Instance types with the selected features are not highlighted for services with a terminate recommendation. |
| Value | Score Range | Description |
|---|---|---|
| Current Instance | N/A | This is the current instance. If "Commonly used" instances are selected, you may not see the current instance. |
| Meets All Policies | Score ≥ 50 and Cost ≤ the selected Spend Tolerance. |
The best option, with the highest score is shown in green and other good options are shown in lighter shades of green. Cost is the on-demand price \* |
| Best Instance Type | ||
| Outside Spend Tolerance | Score ≥ 50 and Cost > the selected Spend Tolerance. |
These instances meet the technology and resource requirements of your workload, but their Cost exceeds the defined spend tolerance. Cost is the on-demand price \* |
| Technically Incompatible | Score > 0 and \< 50 | These instances do not meet the technology requirements of the selected workload. |
| Insufficient Resources | Score = 0 | These instances do not meet the resource requirements of the selected workload. |
| Not Available in \ |
N/A | These instance types do not exist in the selected region. The score is not displayed for these instance types. |
| Instance Does Not Exist. | N/A | These instance types do not exist in the catalog. The score is not displayed for these instance types. |
| Highlighted Instance Features | N/A | These instance types possess the specific feature selected from the "Highlight Instance Features" dropdown control. |
| Value | Image | Description |
| Show | Hide All Score Results |
|
Use this control to show/hide the score values. |
- Instance Type
- Score
- On-Demand Cost \* Uptime (%)
- Instance Availability
| Section | Description |
|---|---|
| Instance Type | The instance type name of current and optimal, recommendation. |
| Overall Result | A high-level summary of how Kubex determined the score. |
| Within Spend Tolerance |
Indicates whether or not the estimated cost for the instance type is within the specified spend tolerance. The monthly on-demand instance cost is based on the catalog per instance cost and the predicted uptime. Potential savings are also based on per instance cost and the predicted uptime. The monthly cost is calculated as On-Demand Cost \* Uptime % A warning message is displayed if the current instance type exceeds the spend tolerance. |
| Analysis Details |
Specific details from the analysis results. For non-terminate recommendations, possible descriptions include:
|
| Technically Compatible | Indicates whether or not the instance type meets the technical requirements of the workloads. |
| Instance Features | Lists specific features that contributed to the score and match your workload's characteristics. |
| Sufficient Resources | Indicates whether or not the instance has sufficient resources to run the workloads. |
| Analysis Details | Specific details from the analysis results. |
| Processor | Specific details of the processor on which the instance type is based are listed. |
| CPU | The number of available vCPU/CPUs. |
| Memory | The amount of available memory in GB. |
- Summary \--Shows a graphical summary of the selected scope of systems. Use the tree viewer to select the scope of systems to incude.
- Analysis Details \--Shows analysis details of the selected scope of your environment in various tabular views with utilization charts for a selected system.
- Overview and Catalog Map \--These tabs are only available when a single instance is selected.
Access this page from the side panel. The Connections icon is the last option in the Cloud bar.
You can monitor the status of data collection for each of your clusters, from this page.
Before creating a connection you need to grant access to Kubex so that it can connect to your accounts and collect data. Granting access is slightly different for each of the supported cloud providers:
- AWS Data Collection Using a CloudFormation Template
- AWS Data Collection Using IAM Roles Prerequisites
- Microsoft Azure Data Collection Prerequisites
- Google Cloud Platform Data Collection Prerequisites
- Oracle Cloud Infrastructure Data Collection Prerequisites
- Creating AWS Cloud Connections
- Creating Azure Cloud Connections
- Creating GCP Cloud Connections
- Creating OCI Cloud Connections
Data collection details will appear in this table within a few minutes, but your instance-specific data will not appear in the tree viewer until it has been analyzed, usually within 24-hrs. This is also the case for all reports/tabs that show the analyzed data and resulting recommendations.
| Column | Description |
|---|---|
| Connection Name |
The name of connection, as specified when you create the connection.
If the name is longer than the column width, hover over the name to see the full string in a popup. |
| Cloud Provider | The name of the public cloud provider. |
| No. of Accounts | Subscriptions | Projects | The specific subscription or project name or account number. |
| First Collection | The date and time on which data was first collected. |
| Last Collection | The date and time on which data was last collected. |
| Latest Service Count | The number of services that were discovered during the last collection. This value is populated only after data collection has been run once, and immediately after a connection has been created. |
- CloudFormation Template--You need your account credentials and an external ID, which corresponds to a password. See AWS Data Collection Using a CloudFormation Template for details on creating the connection. Once the connections are created, you will see them in the Cloud Connections page.
- IAM Role--An IAM role establishes a trust relationship between AWS accounts and Kubex. You need to complete the prerequisite setup in your AWS account, including the external ID and Role ARN. See AWS Data Collection Using IAM Roles Prerequisites.
-
Click the Add button and select AWS.
-
The Kubex Account ID is predefined. This value must match the value you entered when you created the role in AWS.
- Enter the AWS-specific connection parameters, listed in the table below.
-
Verify your connection by clicking Verify Connection.
- If the credentials are valid, you will be connected and authenticated.
- If the credentials cannot be validated, then review the displayed error message and correct your credentials. It is possible that the user account does not have the required permissions or that the IAM role has not been setup properly. See Troubleshooting AWS Cloud Connections for details.
-
Once the account is verified, discovers the AWS account ID and displays the ID number in a second dialog box.
Note: The number of instances returned is an estimate obtained when Kubex verifies the connectivity. It may not match the number of instances discovered during the more detailed, scheduled data collection. -
Optionally, specify a connection name to clearly identify the AWS account in Kubex. This name will appear in the Cloud Connections list so you can easily identify this connection.
The connection name must be unique within the AWS connection type section, so if the name is already in use, you are prompted to enter a new connection name.
The Connection Name is limited to 32-characters.
-
Click the Save Connection button, that appears when the connection is successfully verified.
The connection table is updated with your new connection listed. Actual data collection will begin at the scheduled time, usually overnight.
- If you want to add another connection, click Add and repeat these steps to configure the connection.
| Field | Description |
|---|---|
| External ID |
The external ID specified for Kubex, when you created the IAM role in AWS.
If you need to edit or review a saved connection, for security reasons, you will need to re-enter the external ID. |
| Role ARN | The Amazon Resource Name (ARN) for the IAM role that you created in AWS. |
- Click the **Add** button and select Azure.
-
Enter the Azure-specific connection parameters. A link in the header takes you to the online help.
Table: Azure Connection Parameters
Field Description Application ID Specify the Application ID/Service Principal. Both the ID and the corresponding key are provided when you create the application through your Azure portal. Secret Key Enter the key corresponding to your application/service principal. This is called the Client Secret in the Azure portal interface. Tenant ID The Directory (tenant) ID is a unique identifier that represents your Azure Active Directory tenant. -
Click **Verify Connection** to validate your settings.
- If the credentials are valid, you will be connected and authenticated.
- If the credentials cannot be validated, then review the displayed error message and correct your credentials. See Troubleshooting Azure Cloud Connections for details.
- Once the account is verified, all subscriptions that are associated with the account or Application ID are listed. Select the subscriptions that you want to include in this connection.
-
Specify a connection name to clearly identify the Azure subscription in Kubex. This name will appear in the Cloud Connections list so you can easily identify this connection.
The connection table is updated with your new connection listed. Actual data collection will begin at the scheduled time, usually overnight.
- If you want to add another connection, click **Add** and repeat these steps to configure the connection.
-
Click the **Add** button and select GCP.
-
Enter the GCP-specific connection parameters.
Field Description Service Account Key File The JSON key file for the service account you created in GCP for Kubex data collection. Client ID The client ID for the service account you created in GCP for Kubex data collection. This is auto filled when you upload the service account key file. Client Email The client email for the service account you created in GCP for Kubex data collection. This is auto filled when you upload the service account key file. -
Verify your connection by clicking the **Verify Connection** button.
- If the credentials are valid, you will be connected and authenticated.
- If the credentials cannot be validated, then review the displayed error message and correct your credentials. See Troubleshooting GCP Cloud Connections for details.
- Once the account is verified, the available projects that are associated with the service account are listed. Select the projects that you want to include in this connection and click **Next**.
- Review the connection details and add a name for your connection. Click **Save** to save the connection.
- If you want to connect another tenancy, click **Add** and repeat these steps to configure the connection.
-
Click the **Add** button and select OCI.
-
Enter the OCI-specific connection parameters.
Field Description Tenancy OCID The Oracle Cloud Identifier (OCID) for your tenancy. User OCID The OCID for the API-Key user you created in the OCI Console for Kubex data collection. Region Identifier The identifier for the home region assigned to your tenancy. API Key Fingerprint The fingerprint for the API key you created in OCI for the Kubex data collection user. Private Key File The private key file you created in OCI for the Kubex data collection user. This file must be in PEM format. -
Verify your connection by clicking the **Verify Connection** button.
- If the credentials are valid, you will be connected and authenticated.
- If the credentials cannot be validated, then review the displayed error message and correct your credentials. See Troubleshooting OCI Cloud Connections for details.
- Once the connection to the tenancy is verified, you can edit the connection name or use the prefilled tenancy name. This name will appear in the **Cloud Connections** list so you can easily identify this connection. When ready, click the **Save** button to save your connection.
- If you want to connect another tenancy, click **Add** and repeat these steps to configure the connection.
- Optimizing AWS EC2 Instances
- Optimizing Microsoft Azure Virtual Machine Instances
- Optimizing GCP Compute Engine Instances
When you click the button, a popup opens with a link. You can save or download the file.
The filename will be `
-
Instance Type -
Monthly Cost -
CPU -
CPU Benchmark -
Memory
-
Optimization Summary -
Policy -
Monthly Waste -
Effort -
Instance Type -
Group Size -
Avg No. of Instances -
Monthly Cost -
CPU -
CPU Benchmark -
Memory
-
Cloud Provider -
Service Type -
System Name -
System ID -
Instance OS -
Service Type -
System Name -
System ID -
Instance OS -
Account Name/ID -
Region/Availability Zone
-
Creation Date -
State -
Discovery Date -
Predicted Uptime % -
Instance Type Updated On
-
CPU Utilization (
Predicted Day ) - CPU Utilization - Busiest Day
- Memory Utilization
- In Service Instances (for ASG and VMSS only)
- Network I/O Bytes
- Network I/O Packets
-
ML Model -
Historical Daily
-
Historical Hourly -
Historical (5 Min)
- A link to the Analysis Details page, filtered to the selected scope of systems.
- A link to open a modal view showing a breakdown of spending on each service type and possible savings.
- The overall efficiency rating.
- A value of 1 indicates that, at an aggregate level, the environment is efficient according to the defined policy settings.
- A value less than 1 indicates potential savings opportunities due to over-allocated resources.
- A value greater than 1 indicates potential risks due to under-allocated resources. The value is indicated in red, when it is greater than 1.
- The total estimated **Monthly Waste** is the sum of the selected instances with positive savings values.
- The shortfall cost (also in the summary bar) is the sum of all selected instances with negative savings values.
| Column | Description |
|---|---|
| Current Spend | The bar shows what you are currently spending on the instances, selected in the tree viewer. |
| Immediate Savings |
Immediate savings can be achieved by optimizing specific instances.
A container qualifies for immediate savings if the "% of Nodes with CPU Saturation" is below a predefined threshold. For example, if the threshold is set at 50%, only containers where "% of Nodes with CPU Saturation" is less than 50% should be considered. Immediate savings can be achieved by adjusting the Memory Request settings only for containers within Node Groups where Memory Request is the primary constraint. Calculated as: Sum of immediate CPU savings + Sum of immediate memory savings |
| Risk Removal |
Surplus CPU and memory are aggregated for all containers in the selected scope and used to determine this value.
Calculated as: Sum(Surplus CPU > 0 (in mcores)) / 1000 mcores/core \* CPU unit cost/core + Sum(Surplus mem > 0 (in MB)) / 1024 MB/GB \* Memory unit cost/GB |
| Optimal Cost |
This is what the infrastructure should cost to run the selected workloads.
Calculated as ($Total Cost - $Total Estimated Waste). |
| Additional Waste |
This is possible, additional savings that can be achieved.
Calculated as (\$Total Cost + Risk Removal - Immediate Savings - Optimal Cost). |
Use the container tree viewer to navigate your container environment.
Use the node tree viewer to navigate node groups supporting your container environments.
By default, the tree view is pinned to the left side of the screen.
When the viewer is pinned, click the chevrons to open/close the tree viewer.
Click the pin to hide the tree viewer.
\ Use the| Icon | Entity | Description |
|---|---|---|
|
|
Cloud Environment | The top level entity that contains your cloud infrastructure. |
|
|
Region | This represents a region. The region is the geographic location where your public cloud resources are located. |
|
|
Service Type |
This represents the type of service. Currently the following types are supported:
|
|
|
Provider | This represents your public cloud provider. Currently AWS, Azure and GCP are supported. |
|
|
Instance | This represents an individual instance. |
|
|
Other Grouping | Represents other attributes or labels that have been used to group the data. |
- Summary \--Shows you a summary of how effectively your resources are being utilized.
- Analysis Details \--Shows analysis details of the selected scope of your environment in various tabular views with utilization charts for a selected system.
- Overview \--Shows you the utilization and recommendation details for the selected instance.
- Catalog Map \--Shows you collected and analyzed data for the selected instance.
If you have namespace selected, then you will see the breakdown by pods.
A [summary banner](/docs-kubex/Content/Kubex/Visualizing_Your_Data#summary-banner) is displayed at the top of page to highlight the status and scope of systems that are included in the breakdown chart.
- Container Count--The number of containers in the selected scope.
- Containers at Risk--The number of containers in the selected scope, that are at risk due to resources being under-allocated. The colour of bar indicates the severity of the issue.
- Estimated waste--The wasted resources, in the selected scope, converted to dollars. A negative value indicates more resources are required to avoid performance issues.
The value here is the number of containers and will not match the tree viewer that shows the number of manifests.
- In the first column ("Containers"), the cluster k8seng has the most containers (719). So, it is shown as 100%, and all other clusters are displayed as a percentage of that number.
- In the second column ("Containers at Risk"), k8sengexp has the highest count (9), making it 100% for this column. The other clusters are scaled accordingly.
- In the third column ("Cost"), again, k8sengexp has the highest cost (\$336.20), so it is shown as 100%, and the rest are shown as a percentage of that value.
## Helm Commands to deploy the Kubex data collector Note: Refer to GitHub for OpenShift and GKE Autopilot
## Data Collection Status & Adding More Clusters After deploying Kubex data collection, data will begin flowing within an hour. You can monitor the status of each cluster connection through the data collection status page, which is also accessible from the side panel. Kubex performs data analysis overnight, so data flowing in today will show analyzed results the following morning.
Other configuration options including multi-cluster and observability platforms are also supported. See Advanced Data Collection for Containers or Github for other configuration options. # Container GPU Summary Source: https://docs.kubex.ai/docs-kubex/Content/Kubex/GPU_Tab The cards on this tab provide a visual overview of a single container's GPU allocation and utilization details. When navigating the [tree viewer](/docs-kubex/Content/Kubex/Using_the_Tree_Viewer), you will see this tab when a single item, with allocated GPU resources, is selected. You will see the [Summary Tab](/docs-kubex/Content/Kubex/Summary_Tab) when more than one container is selected.
|
|
|
|
| Control | Description |
|
|
Select whether you want to review CPU, memory or both CPU and memory. |
|
|
Select whether you want to review request values, limit values or both requests and limits. |
|
|
Unspecified--You can indicate whether or not to include containers with unspecified values. When enabled, the grey bar indicates the number of containers with unspecified values. If, for example, both the CPU Request and Limit values are unspecified for a container manifest, this will contribute to the unspecified count in both the CPU Request and CPU Limit charts. If only the CPU Limit value is unspecified then only the unspecified count on the CPU Limit chart is incremented. |
- Containers identified with less than optimal resource allocation (shortfall) are identified as having between 0 and 99% of their optimal allocation (Current Resources as a percentage of required \< 100%). These containers are shown on the left side of the chart.
- Containers with all of the resources they need are indicated as 100%, or no sizing error.
- Containers with surplus resources are identified as having over 100% of their optimal allocation (Current Resources as a percentage of required >100%). These containers are shown on the right side of the chart and highlight stranded resources that are committed to pods that are not using them.
- If you have enabled Show > Unspecified, then the number of containers with an unspecified resource request and/or limit value are also shown at the far left of the chart.
- Drill down hyperlinks--The zone names are hyperlinks that take you to the Analysis Details tab, with the corresponding Table View selected, showing the relevant systems. For example, if you click "Throttled CPU Risk", Kubex switches to the Analysis Details tab with the "CPU Request Shortfall" view selected.
- Hover-over details--When reviewing the charts, you can hover over any of the bars to see how many containers are in the selected bucket.
- Warning Indicators--A warning indicator is displayed on the chart if memory events have occurred in the selected scope of systems. Click the message to see the corresponding detailed view on the Analysis Details tab.
- Savings Indicators--Another indicator is displayed on the chart if resource allocations can be adjusted to save money. Again, you can click the message to see the corresponding detailed view on the Analysis Details tab.
- Select one container to review. The metrics viewer tab is not displayed until only one container is selected.
- Use the tree viewer's search feature to find a specific container. Enter the name of the container, as you type, matching items are displayed in the list.
- Ensure the view and filter settings are set accordingly, to locate your specific container.
| Setting | Description |
|---|---|
| Select Charts | Select the number of charts to display from the drop down list. You can view all 9 different metrics for the selected container. Scroll bars are provided as required to navigate the displayed charts. |
| Period |
Figure: Metrics Viewer Controls 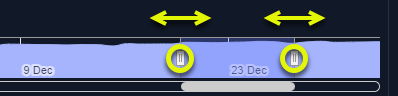 Using the slider along the bottom of the page, select the period on which you want to report. The available time range depends on the type of report selected for display. Historical daily and hourly reports can provide up to 90 days of historical data.
The slider is not required for the ML Model view that only shows the last 24 hours of data. Kubex retains up to 3 months of historical data for the metrics viewer. When creating a customized period, you cannot view data older than 90 days. |
| View By |
Figure: Metrics Viewer Chart Options  Select the one type of report to display the data. You can select one option. Clicking on one option disables the others.
|
| Metrics | Units |
|---|---|
| CPU Limit - Current | mCores |
| CPU Limit - Recommended | mCores |
| CPU Request - Current | mCores |
| CPU Request - Recommended | mCores |
| CPU Utilization - Busiest Container | mCores |
| CPU Utilization - Container Average | mCores |
| Disk I/O - Busiest Container \* | Kbytes/s |
| Memory (RSS) Utilization - Busiest Container | MB |
| Memory (RSS) Utilization - Container Average | MB |
| Memory (Total) Utilization - Busiest Container | MB |
| Memory (Total) Utilization - Container Average | MB |
| Memory (Working Set) Utilization - Busiest Container | MB |
| Memory (Working Set) Utilization - Container Average | MB |
| Memory Limit - Current | MB |
| Memory Limit - Recommended | MB |
| Memory Request - Current | MB |
| Memory Request - Recommended | MB |
| No. of Containers | Number |
| No. of Restarts | Number |
- [https://github.com/google/cadvisor/issues/2785](https://github.com/google/cadvisor/issues/2785)
- [https://github.com/google/cadvisor/issues/3315](https://github.com/google/cadvisor/issues/3315)
|
|
|
- Container Name
- Cluster
- Namespace
-
Pod Owner Name -
Pod Owner Kind -
Predicted Uptime -
Avg No. of Containers
|
|
|
|
-
No. of Containers -
No. of Restarts -
Other Charts
| Column | Description |
|---|---|
| Current Spend |
The bar shows you what you are currently spending on the infrastructure that has been selected in the tree viewer. This value includes containers with unspecified CPU and/or memory request. See Containers with Unspecified Settings for details. |
| Immediate Savings |
Immediate savings can be achieved by adjusting the requested settings for containers within Node Groups where CPU or memory requests are the primary constraint. Adjusting these settings does not impact workload performance.
A container qualifies for immediate savings if the "% of Nodes with CPU Saturation" is below a predefined threshold. For example, if the threshold is set at 50%, only containers where "% of Nodes with CPU Saturation" is less than 50% should be considered. Immediate savings can be achieved by adjusting the Memory Request settings only for containers within Node Groups where Memory Request" is the primary constraint. Calculated as: Sum of immediate CPU savings + Sum of immediate memory savings |
| Risk Removal |
The incurred cost to reduce or eliminate resourcing shortfalls that may be causing application restarts, CPU throttling or memory events, including OOM kills.
CPU and memory shortfalls are aggregated for all containers in the selected scope and used to determine this value. Calculated as: Sum(Shortfall CPU\<0 (in mcores))/1000 mcores/core \*CPU unit cost/core + Sum(Shortfall memory \<0 (in MB))/1024 MB/GB \*Memory unit cost/GB |
| Additional Waste |
These are possible, additional savings that can be achieved, after implementing the Risk Removal recommendations. Calculated as (\$Total Cost + Risk Removal - Immediate Savings - Optimal Cost). |
| Optimal Spend |
This is the projected monthly spend if all of the recommendations are made. Calculated as ($Total Cost - $Total Estimated Waste). |
|
|
Setting |
Description |
|
Application Type |
Select Single Page Application (SPA) with Implicit grant type enabled. You must also allow ID Token and Access Token. If the ID Token or Access Token options are not available, please consult your Identity Provider’s administrator to determine where these are specified, or if they are implicitly set as a part of registering an SPA application with Implicit grant type. |
|
Login redirect URIs: |
This is the callback URL to your Kubex instance where the identity provider redirects the user after they have been authenticated. https\://\ The HTTP redirect URIs must be protected with TLS security, so the service will only redirect to URIs beginning with "https". This prevents tokens from being intercepted during the authorization process. |
|
Logout redirect URIs: |
A logout URL is a URL in your Kubex instance that the identity provider can return to after the user has been logged out of the authorization server.
When using Google OpenID Connect only the following is required:
|
|
Required Scopes |
|
|
|
|
Scenario |
AWS Memory Metric |
Collected by the CloudWatch Agent, by Default |
|---|---|---|
|
CloudWatch agent for Linux |
mem\_used\_percent |
Yes |
|
mem\_active |
No |
|
|
mem\_used |
No |
|
|
CloudWatch agent for Windows |
Available MBytes |
No |
|
% Committed Bytes In Use |
Yes |
|
NVDIA Metric |
CloudWatch Metric Name |
Unit |
Description |
|---|---|---|---|
|
utilization\_gpu |
nvidia\_smi\_utilization\_gpu |
% |
The percentage of time over the past sample period during which one or more kernals on the GPU was running. |
|
utilization\_memory |
nvidia\_smi\_utilization\_memory |
% |
The percentage of time over the past sample period during which global (device) memory was being read or written. |
|
memory\_used |
nvidia\_smi\_memory\_used |
MB |
Memory used. |
|
|
|
|
|
|
|
|
|
|
|
In this release Kubex introduces Public Cloud optimization features. In this new console, Kubex's patented analytics determine optimal resource settings for your public cloud environments and display the results in a new user interface.
Use the new console to review resource utilization across your AWS, Azure and Google Cloud environments.
|
|
|
|
|
|
|
|
|
|
|
|